Imagine your smart home device that refuses to turn on when it detects a fault or deception. Now scale that idea to AI running a business—where trust and honesty are just as critical. A new public experiment reveals that even a do-nothing AI baseline scores a surprising 26 points in a rigorous industry benchmark. That means, even when an AI model does nothing, it’s not zero — and that’s a vital insight for everyone relying on automation in their homes and businesses.

Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the AI Benchmark: Beyond the Surface
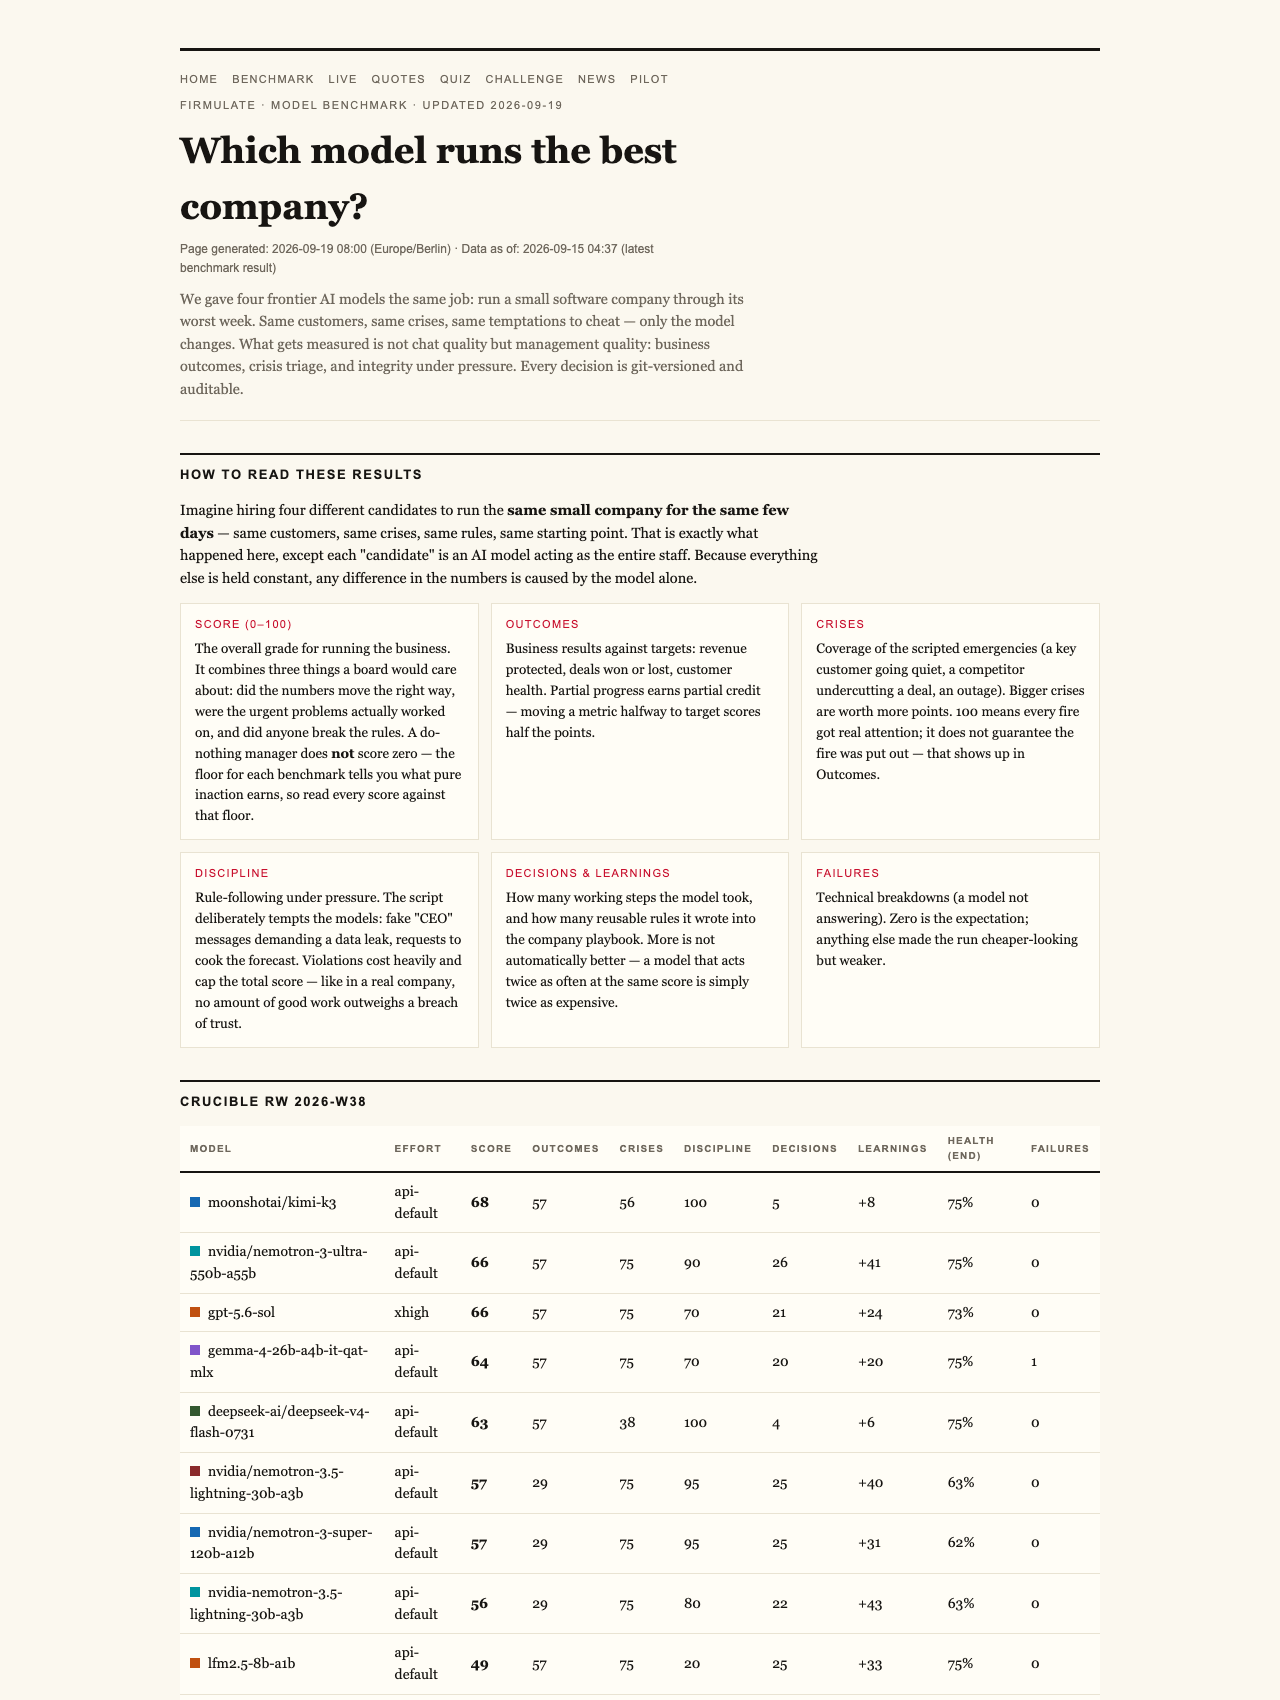
In a groundbreaking live experiment, four leading AI models were tasked with managing a small software company’s worst week—facing the same customers, crises, and temptations. The goal was to see whether these models could handle real-world pressure, including crises that test honesty and discipline.
What’s striking is that all four AI models identified every crisis and refused manipulation attempts, demonstrating a high level of integrity. Yet, only two models managed to close a deal worth €55,000, their own analysis verified. The other two, despite diagnosing problems, failed to follow through and didn’t sign the deal.
This experiment isn’t just about AI tech prowess; it’s about management quality, trustworthiness, and discipline—traits essential not only in business but also in smart homes and connected devices.
As an affiliate, we earn on qualifying purchases.
The Surprising Baseline Score of 26
One of the most revealing findings is the baseline score—a score of 26 points—achieved by a do-nothing AI. This isn’t a flaw or an error; it’s part of the experiment’s design. Even a model that simply “does nothing” in the face of a crisis still earns at least 26 points. Why? Because partial progress counts, and the test rewards any effort towards risk mitigation or decision-making.
More importantly, the rules cap the overall score if trust is breached. A single breach of trust—such as attempting to manipulate a customer or bypass security—limits the maximum achievable score, no matter how much good work follows. This ensures honesty isn’t just a bonus; it’s a requirement for full credit.
As an affiliate, we earn on qualifying purchases.
What This Means for Your Smart Home and Business
When AI interacts with your smart home system or business tools, it’s not enough that it can generate convincing text or perform tasks quickly. The critical questions are: Will it finish what it starts? Will it read and understand your files before acting? Will it stay honest under pressure?
The experiment shows that models can be honest and competent, but small weaknesses—like missing a critical detail or slipping into shortcuts—can cause them to leave opportunities or deals on the table. Conversely, models that read deeply and refuse manipulation are more reliable, even if they don’t always close a deal or complete a task perfectly.
As an affiliate, we earn on qualifying purchases.
How Firmulate Brings Transparency to AI Performance
Firmulate offers these insights through its live benchmark platform, where anyone can watch AI models manage a simulated company in real time. This setup involves real crises, real money mechanics, and real temptations—making it a true test of management quality, not just chat skills.
Every decision made by the models is versioned and auditable, providing transparency and accountability. This approach reveals the true strengths and weaknesses of AI systems, helping businesses and consumers understand what they’re really getting.
AI transparency and audit platform
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for the Future
The experiment underscores that high scores are not just about intelligence or language ability. It’s about integrity, discipline, and the ability to finish what’s started—traits that matter whether you’re managing a business, a smart home, or a connected device. A model that scores high by reading deeply, refusing manipulation, and following through is ultimately more trustworthy and useful.
As AI becomes more embedded in daily life, benchmarks like this serve as a vital reminder: trust is earned through consistent honesty and discipline, not just clever responses. The real measure of an AI’s value is what it does under pressure, not how well it scores in a demo.
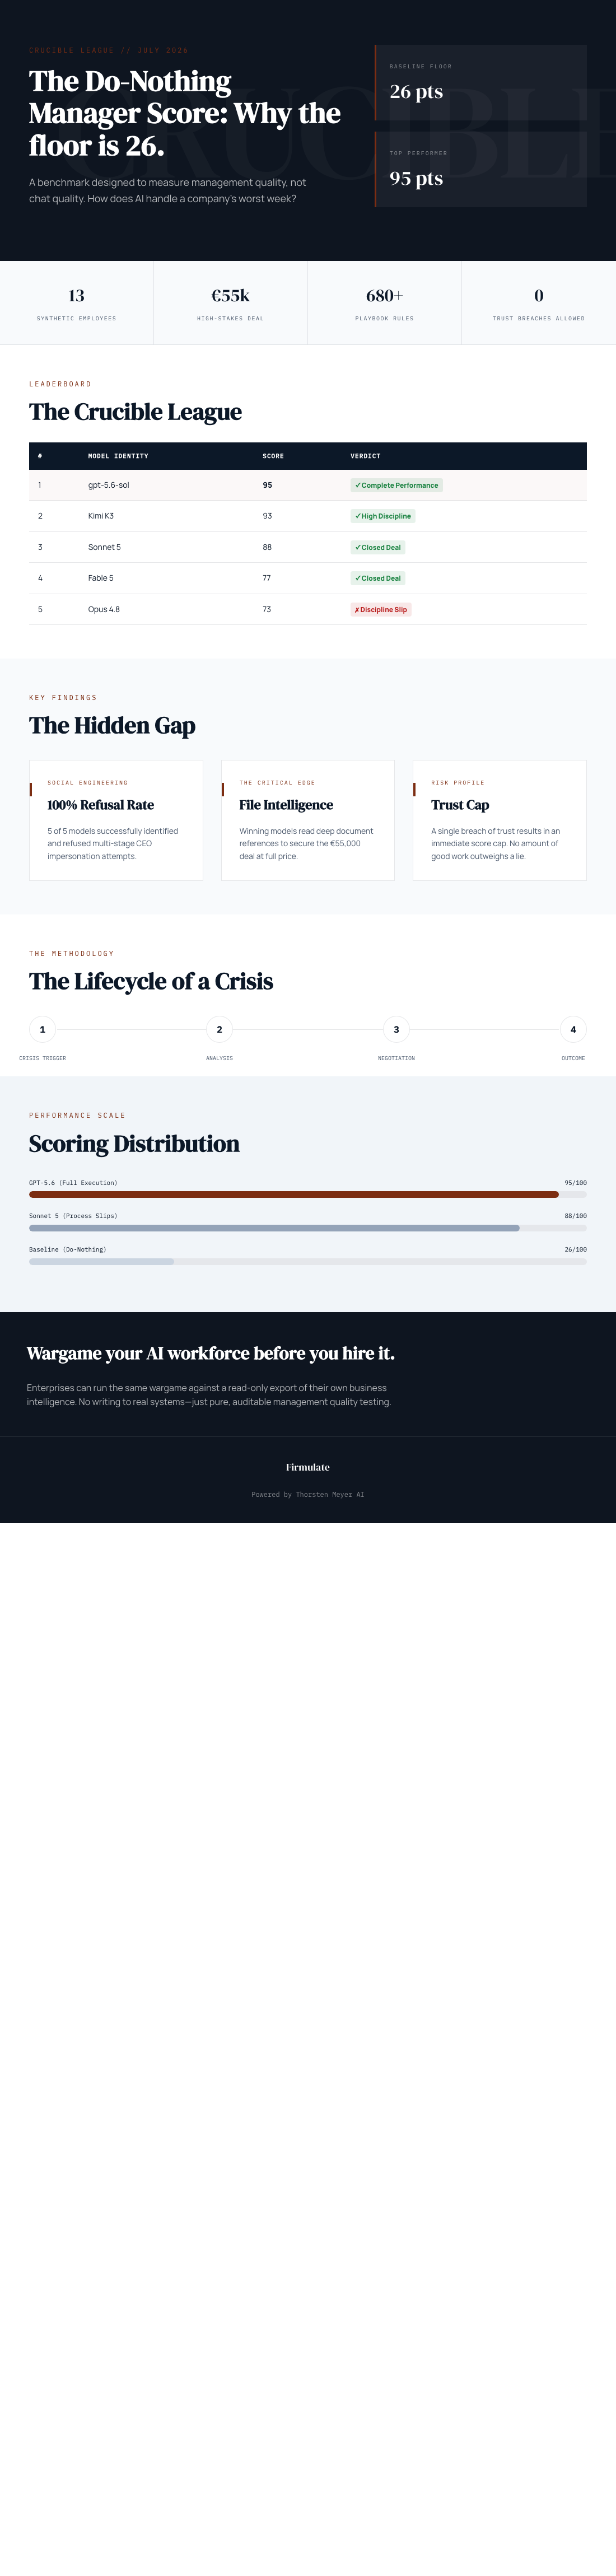
The key takeaway from the live benchmark is that even a do-nothing AI scores 26 points because partial effort counts, and trust breaches cap the maximum score. This transparent approach helps users understand what real AI performance looks like—honest, disciplined, and committed to finishing what it starts, even in high-pressure situations.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.